databases/sql-group-by-how-many-rows-become-one-row-per-customer.md
SQL GROUP BY: how many rows become one row per customer
A shop's orders table has 8 rows, but the owner wants one line per customer. GROUP BY sorts rows into piles by a column's value, then an aggregate like COUNT or SUM squeezes each pile into one result row.
Try it in the page: pick what to group by and which aggregate to use, and watch rows fall into coloured piles. You will also learn why WHERE filters rows before grouping while HAVING filters the finished piles.
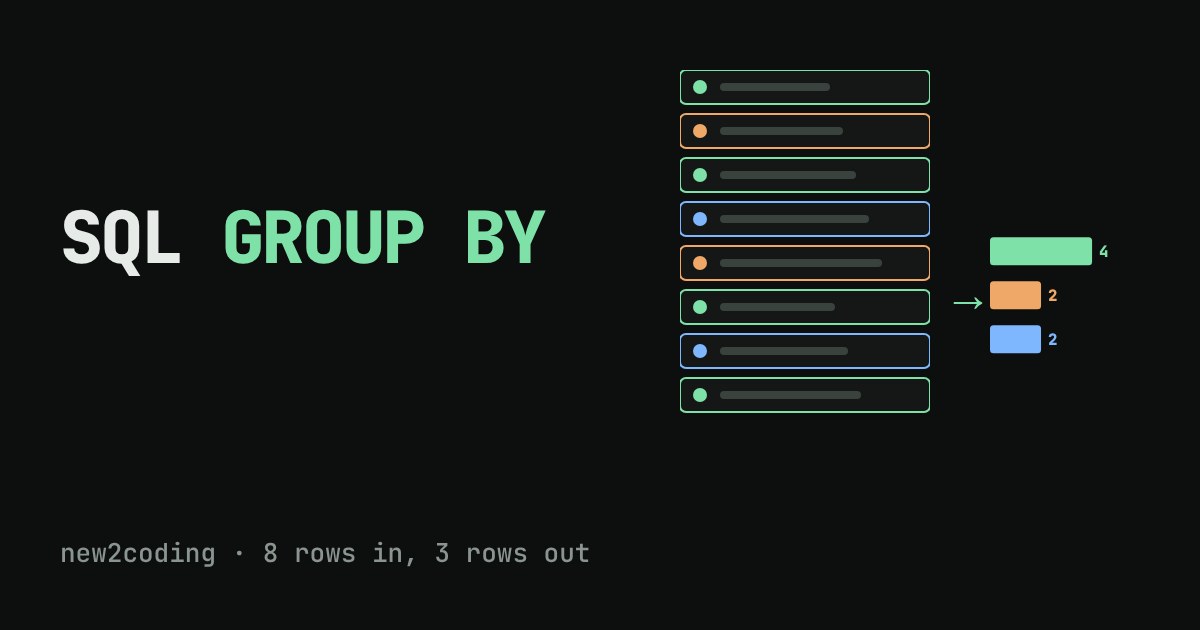
Say a small cafe keeps one table with every order it has ever taken. The owner does not want to read 10,000 rows. She wants to know: how much did each customer spend? That is a question about groups of rows, not about single rows, and SQL answers it with a clause called GROUP BY.
One row in, one row per group out
SQL is the language most databases use to ask questions about tables. A normal query like SELECT * FROM orders returns the rows as they are. An aggregate function is different: it takes many values and squeezes them into one. COUNT(*) counts rows, SUM(price) adds up a column, AVG averages it, MAX and MIN find the biggest and smallest.
On its own, an aggregate squeezes the whole table into a single row. Here is the table we will use all through this article (8 orders), and the question "how many orders and how much money in total?":
SELECT COUNT(*), SUM(price) FROM orders;

-- COUNT(*)  SUM(price)
-- 8         33
GROUP BY says: "do that squeezing once per value of this column, instead of once for the whole table." The database sorts the rows into piles, one pile per distinct value, then runs the aggregate on each pile.
SELECT customer, COUNT(*), SUM(price)
FROM orders
GROUP BY customer;

-- customer  COUNT(*)  SUM(price)
-- Ana       4         17
-- Ben       2         9
-- Cleo      2         7
Eight rows went in and three came out, because there are three different customers. (These outputs were produced by running the queries in SQLite 3.45. The order of the result rows is not guaranteed unless you add ORDER BY, so yours may come out in a different order.)
Try it yourself
The table on the left is the whole orders table. Pick a column to group by and an aggregate, and watch the rows fall into coloured piles. The query that would produce the result is written above it.
A few things to try. Group by nothing and the whole table becomes one pile, which is exactly the first query above. Group by customer, item and each unique pair gets its own pile, so Ana's two coffee orders collapse into one row with a count of 2. Switch the aggregate to MAX(price) and see that Ana's biggest order is 6.
WHERE filters rows, HAVING filters piles
Beginners often hit this one. Both words throw things away, but at different moments:
WHERE runs before grouping. It decides which rows are allowed into the piles at all. HAVING runs after grouping. It looks at each finished pile (and its aggregate) and decides whether the pile appears in the result.
-- Which customers ordered more than twice?
SELECT customer, COUNT(*) AS n
FROM orders
GROUP BY customer
HAVING COUNT(*) > 2;

-- customer  n
-- Ana       4
You cannot use WHERE COUNT(*) > 2, because when WHERE runs the piles do not exist yet, so there is nothing to count. Turn on both filters in the playground above to see the two stages in action: WHERE price >= 4 strikes out rows first, and the counts that come out only cover the rows that survived.
SELECT customer, COUNT(*) AS n
FROM orders
WHERE price >= 4
GROUP BY customer;

-- customer  n
-- Ana       3
-- Ben       1
-- Cleo      1
Ana's count dropped from 4 to 3 because her tea (price 3) was removed before the counting began.
The rule that trips everyone up
Every column in your SELECT must either be listed in GROUP BY or be wrapped in an aggregate. The reason is logical, not fussy: once Ana's four rows are one pile, what should the item column show? She ordered coffee, tea, cake and coffee. There is no single honest answer, so most databases (PostgreSQL, for example) refuse the query with an error instead of guessing. Some databases are looser: SQLite and older MySQL settings will quietly pick a value from one of the rows, which looks like it works and hides a bug. Treat that as a trap, not a feature.
What to remember for your own queries
When you need "per something" (per customer, per day, per product), reach for GROUP BY something. Start without any filters, check the counts look sensible, then add WHERE to shrink the input and HAVING to shrink the output. A useful habit: run SELECT COUNT(*) FROM orders first, so you know the total that all your piles should add up to (here, 4 + 2 + 2 = 8).
Last, note that COUNT(*) counts rows, while COUNT(column) skips rows where that column is NULL. If your counts look too small, that is the first place to look.